MMuflih Imaduddin
All projects

SBERT vs. GPT grading

Can a small fine-tuned model grade short answers as well as GPT?

Role
Undergraduate Thesis
Timeline
Apr 2026 – present
Stack
PythonOpenAISBERT
Links
Colab
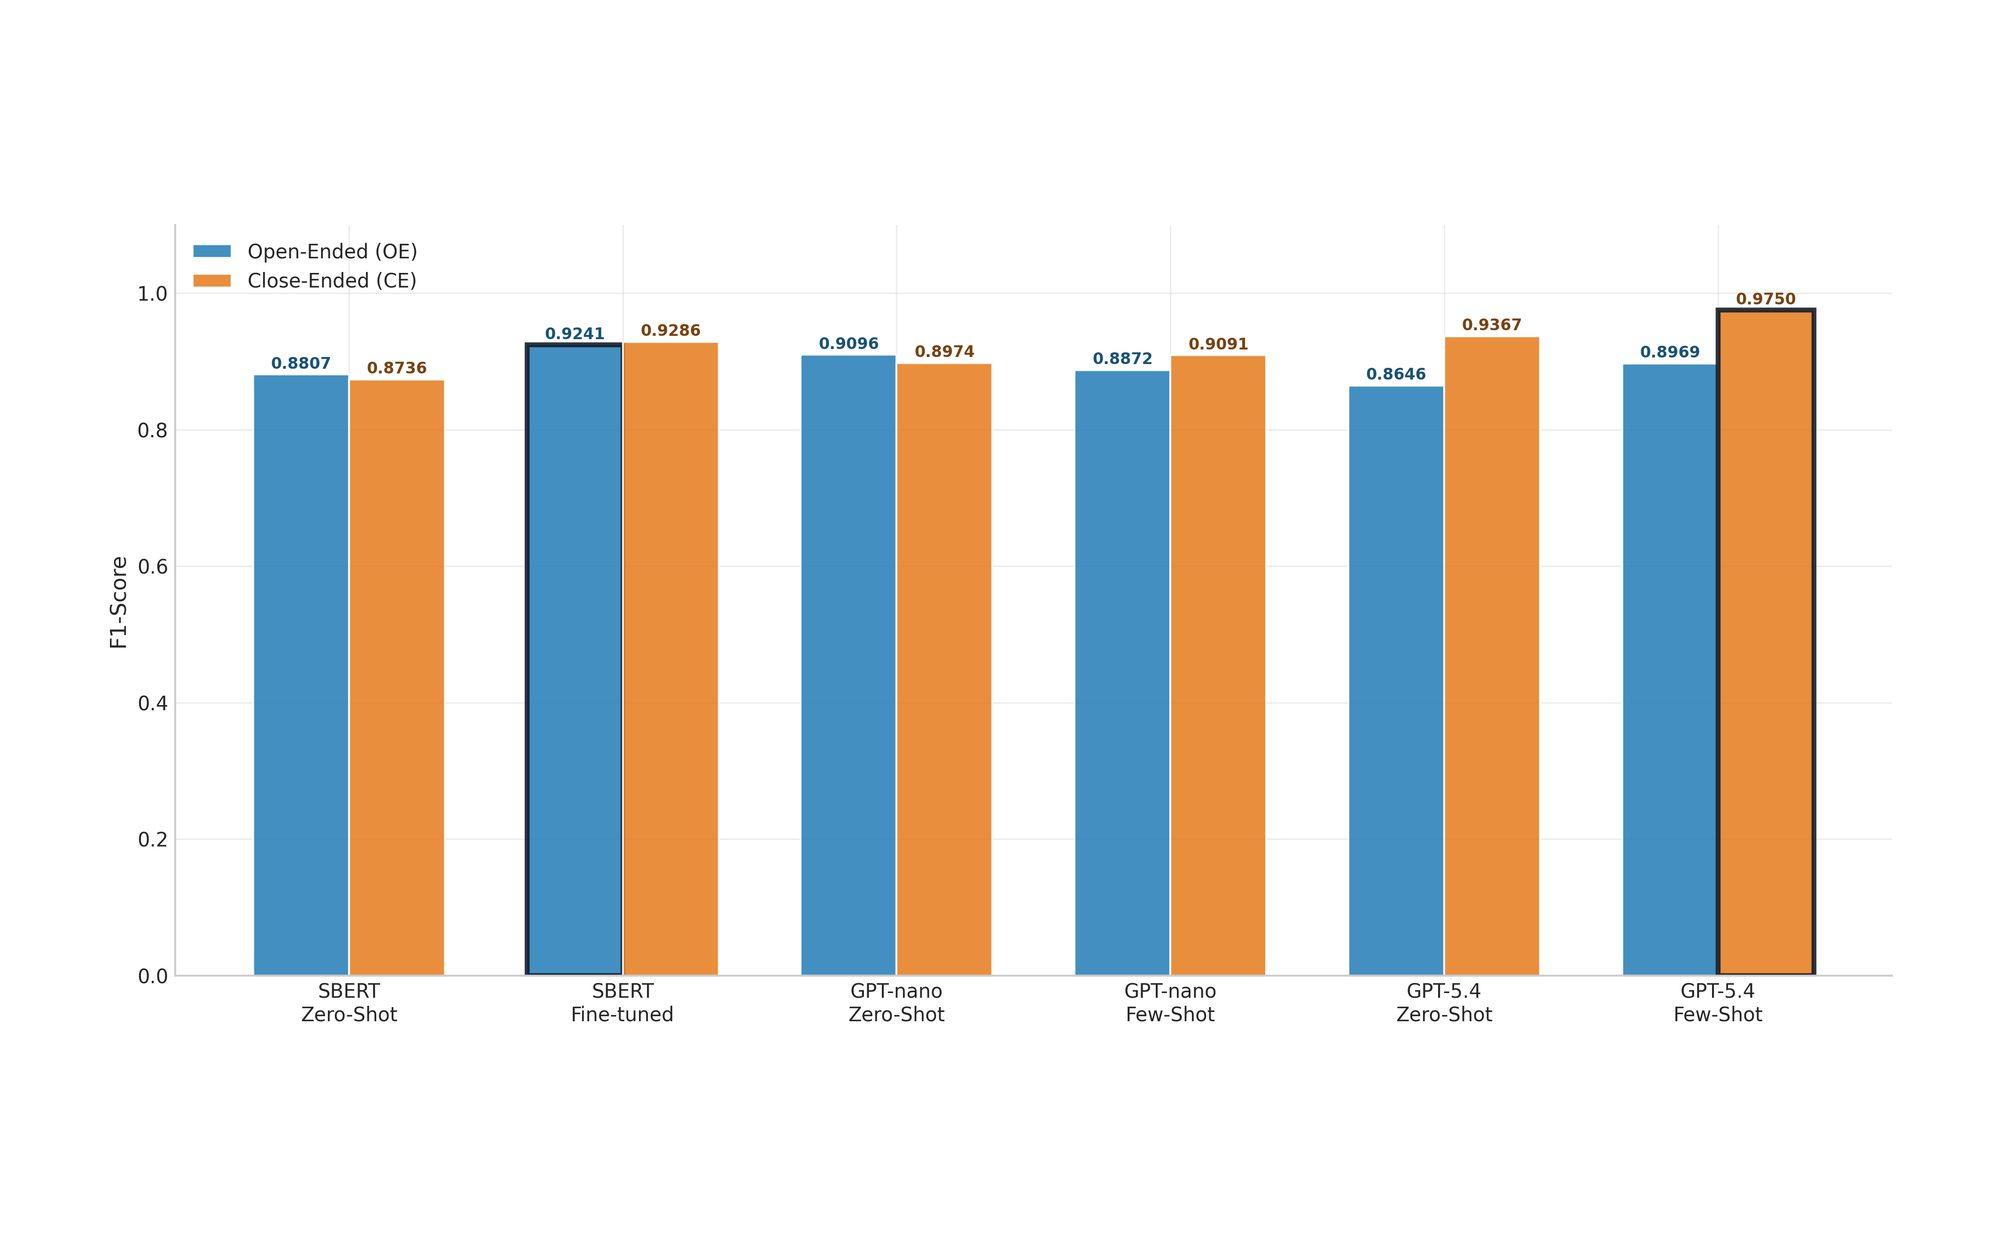
Bar chart of F1 scores for the six grading methods on open-ended and close-ended questions

Problem

Grading short answers by hand is slow; automated graders need to be accurate and affordable.

My role

Built the grading pipeline, an LLM-based data augmentation step and the benchmark.

Result

Fine-tuned SBERT led on open-ended questions (F1 0.92) at zero API cost; GPT-5.4 few-shot led on close-ended questions (F1 0.98).

Overview

An Automated Short Answer Grading (ASAG) system that evaluates student answers with fine-tuned Sentence-BERT and GPT models, benchmarked side by side.

What I built

  • Built an LLM-driven augmentation pipeline that creates paraphrased and contradictory answers to balance the dataset.
  • Fine-tuned Sentence-BERT models and tested GPT prompting strategies (zero-shot and few-shot).
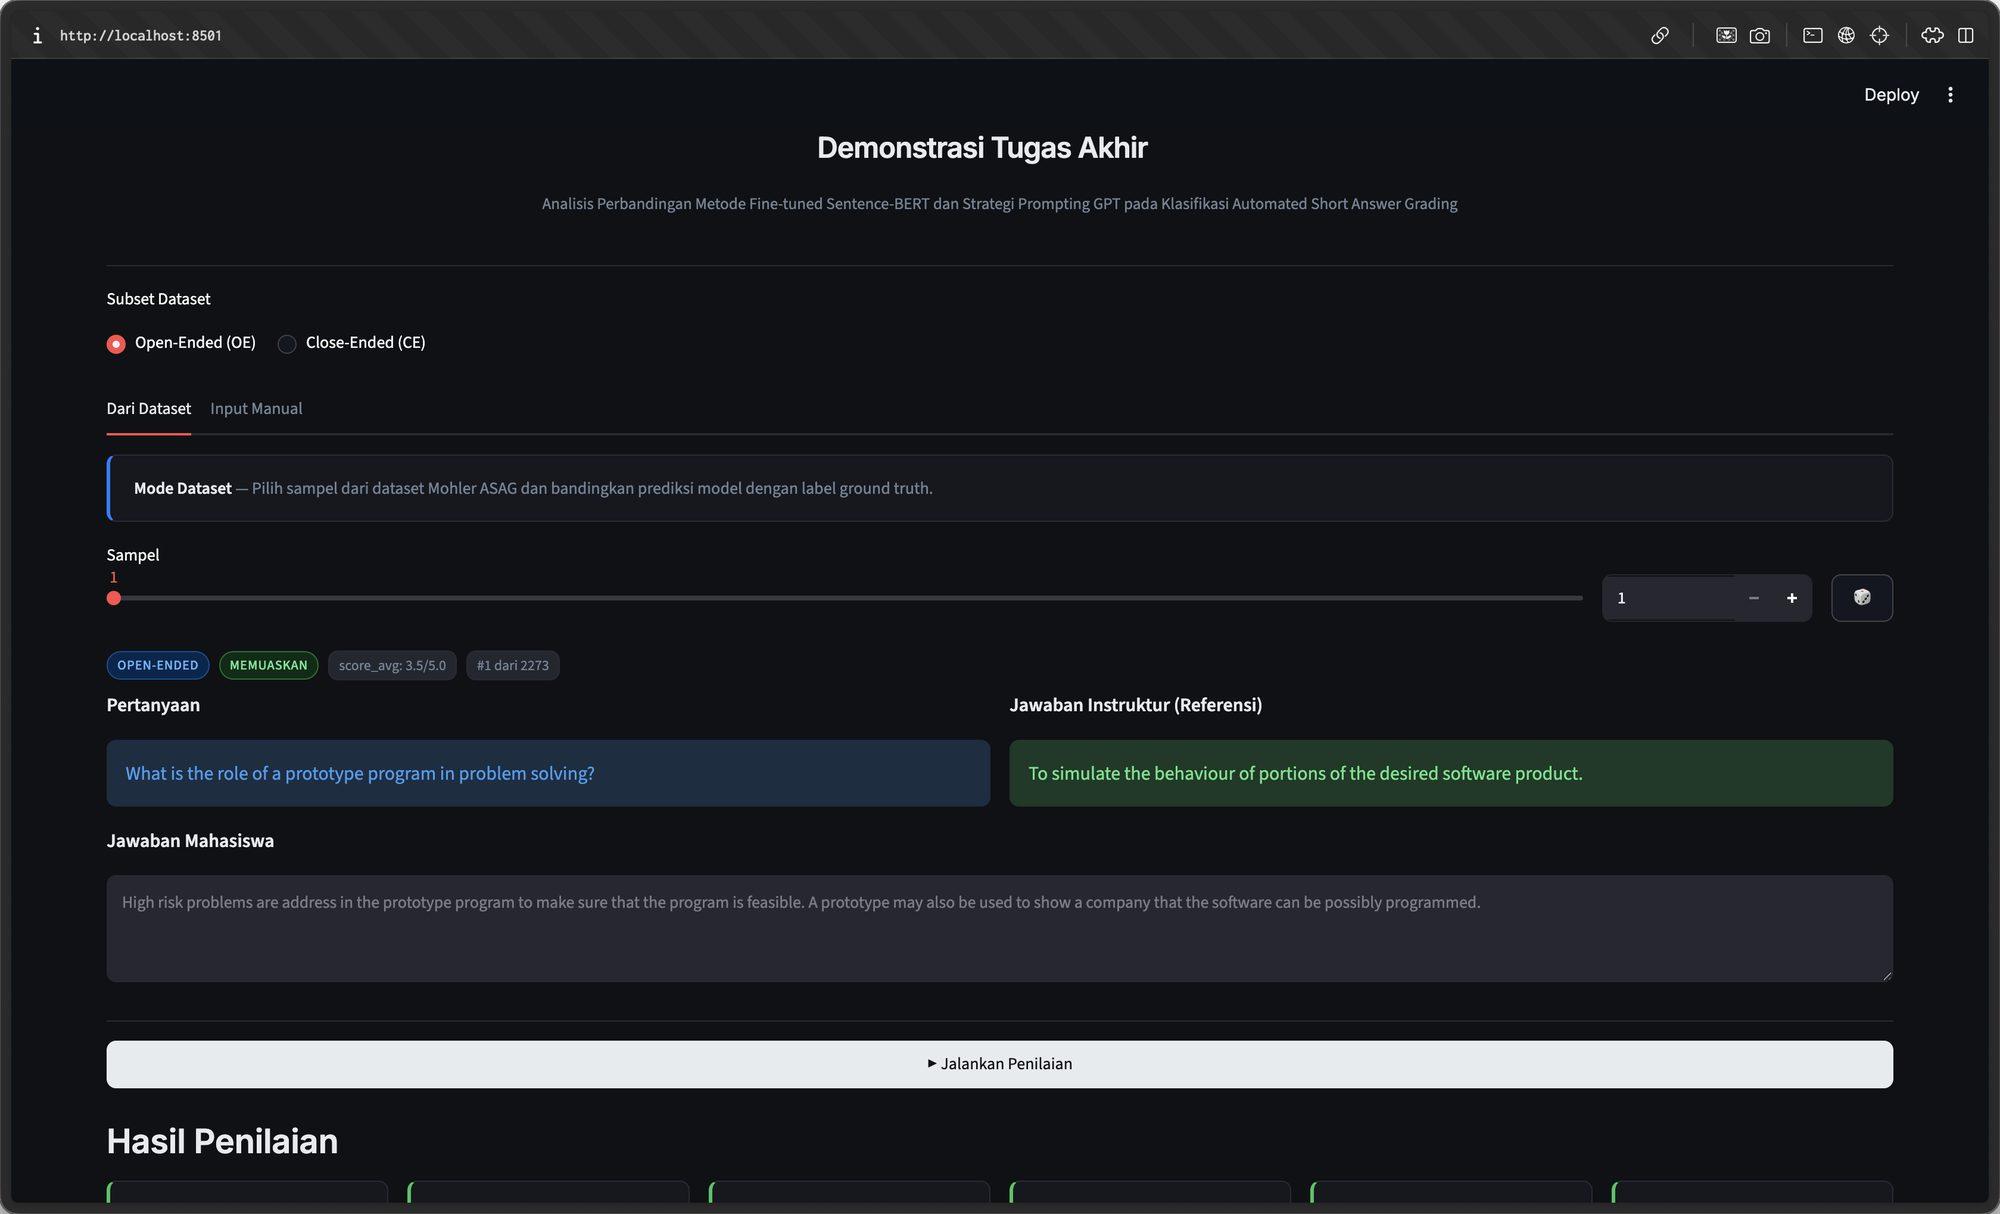
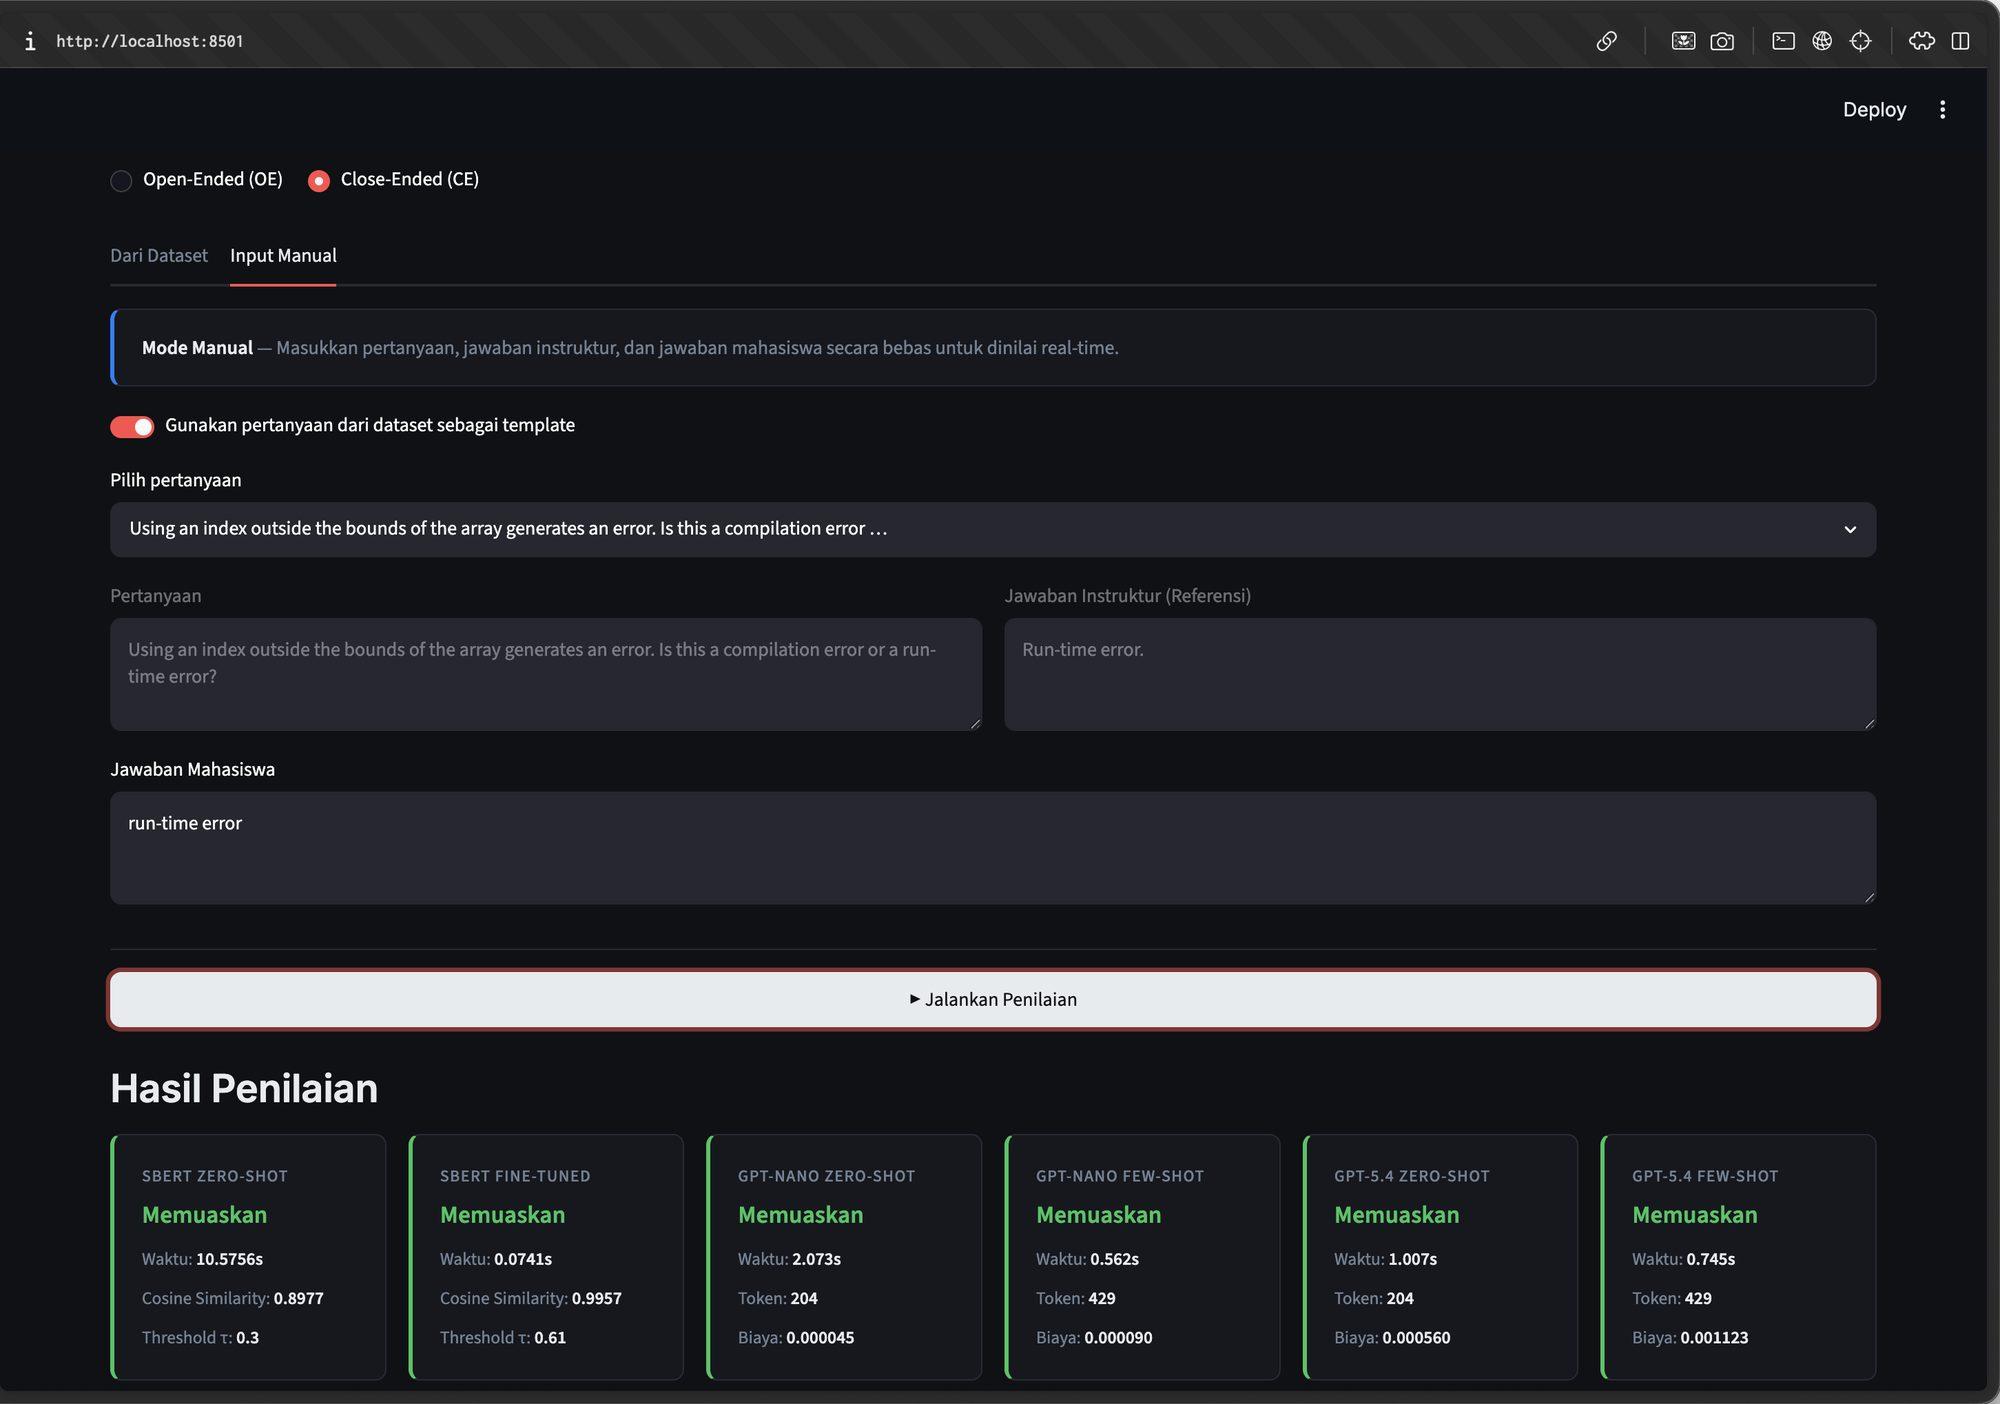
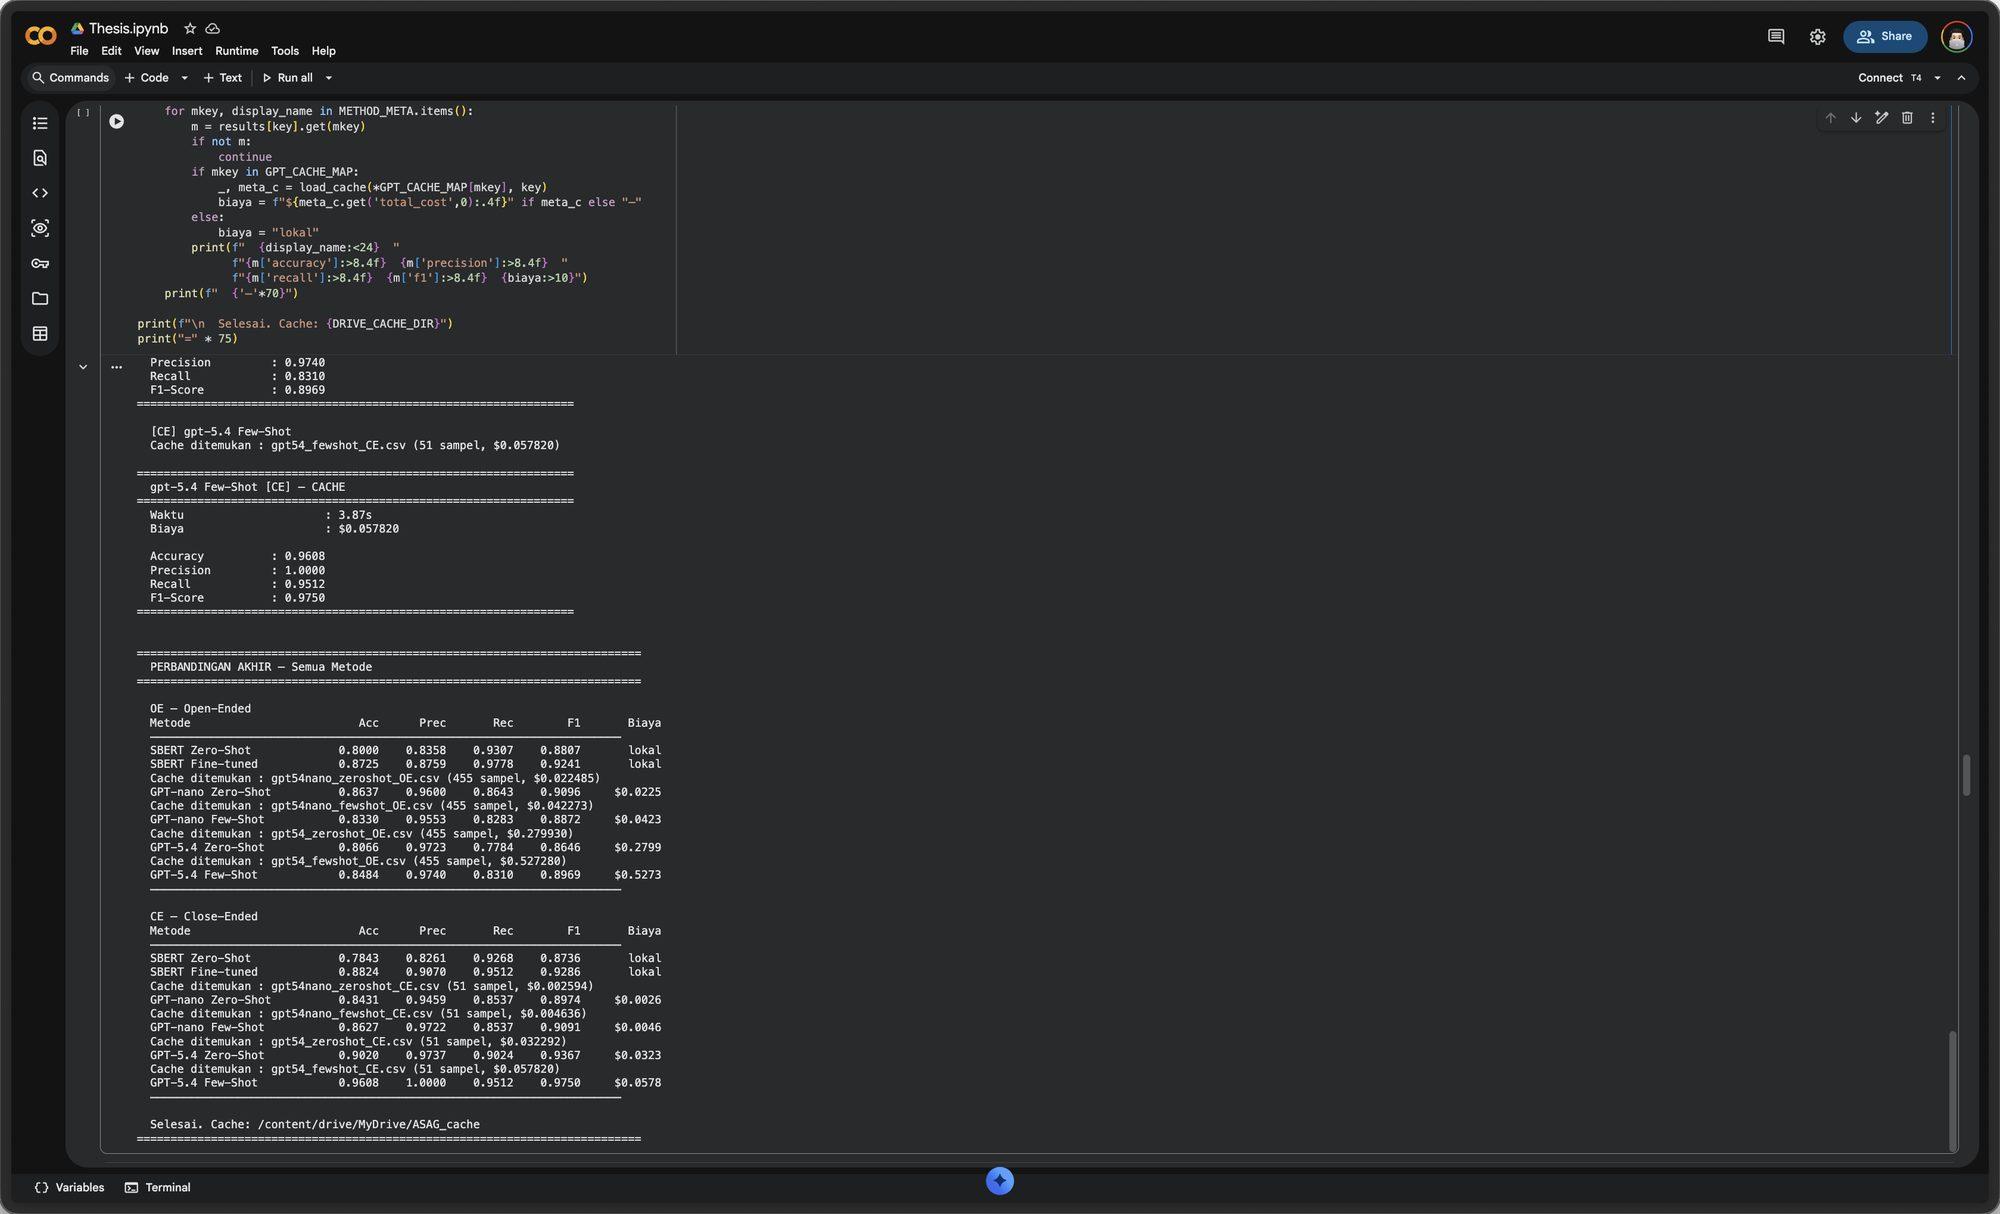
  • Benchmarked F1-score, accuracy and API inference cost, and built a demo app.

Results

0.92

F1 on open-ended questions with fine-tuned SBERT, the best of six methods

0.98

F1 on close-ended questions with GPT-5.4 few-shot

2,442

student answers in the Mohler dataset

Screenshots

Demo app showing a question, the reference answer and a student answer from the datasetDemo app grading a manually entered answer with all six methods side by sideColab notebook printing the final comparison table for every method
Next projectSIMAK Undip